

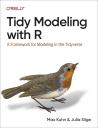

Max Kuhn and Julia Silge introduce tidymodels, a collection of R packages for modeling and machine learning that share the design philosophy, grammar, and data structures of the tidyverse. The book has two goals: to show you how to use these packages to build high-quality statistical and machine learning models, and to help you develop sound methodology that avoids common pitfalls.
It is written for data analysts, business analysts, and data scientists at any level of modeling experience.
Readers should know basic statistics, such as variance, correlation, and linear regression, and be at least a little familiar with dplyr, ggplot2, and the pipe.
Rather than serving as a reference on statistical methods, the book explains models in an intuitive, less mathematical way and focuses on the practical process of building them, using a housing price data set as a running example.
With this book, you will learn how to:
- Split and budget your data for training and testing
- Fit models with
parsnipand bundle preprocessing and models with workflows - Engineer features with
recipes - Measure model performance with
yardstickand estimate it with resampling - Tune hyperparameters with grid search and iterative search
- Compare and screen many models at once
- Apply dimensionality reduction and encodings for categorical predictors
- Explain model predictions and judge when to trust them
The complete book is available to read online for free.


