

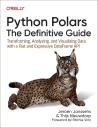

Polars is a Python package for transforming, analyzing, and visualizing data, built with speed and performance in mind.
In this hands-on guide, Jeroen Janssens and Thijs Nieuwdorp walk through its features using real-world tasks such as data wrangling, exploratory data analysis, and building pipelines.
The book is written for data analysts, data engineers, data scientists, and anyone else working with data in Python.
Experience with pandas is not required, but readers coming from it get a dedicated chapter on how the two packages differ and which habits to unlearn.
The book is organized into five parts: Begin, Form, Express, Transform, and Advance. At its heart is a thorough treatment of expressions, the building blocks of every Polars query, followed by chapters that apply them to selecting, filtering, aggregating, joining, and reshaping data. The final part looks under the hood at how Polars is built and why it is so fast, and an appendix, written in collaboration with NVIDIA and Dell Technologies, benchmarks Polars on the GPU. Each chapter ends with key takeaways.
You will learn how to:
- Read and write data from CSV, Parquet, spreadsheets, databases, and the cloud
- Build queries with expressions and combine them effectively
- Work with text, temporal, and nested data types
- Choose between the eager and lazy APIs
- Visualize data with Altair, hvPlot, plotnine, and Great Tables
- Extend Polars with your own Python functions and Rust plugins
- Speed up queries with the GPU engine
All code and data from the book are available on GitHub, and the first chapter can be downloaded as a free sample.


