

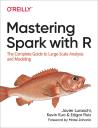

Written by Javier Luraschi, Kevin Kuo, and Edgar Ruiz, this book shows R users how to use Apache Spark to tackle big data and big compute problems. It is meant to take readers who are new to Spark, R, or both and help them become proficient with the tools, skills, and practices of large-scale data science, while also covering topics that interest advanced users.
The book centers on sparklyr, the R interface to Spark.
It begins with the motivation behind Hadoop and Spark, gets you connected to a local cluster, and then works through analysis and modeling with familiar R tools such as dplyr and ggplot2.
Later chapters cover the practical realities of running Spark at scale: choosing and connecting to clusters on premises or in the cloud, reading and writing data in many formats and storage systems, and tuning performance.
The final chapters dig into advanced territory, including running arbitrary R code across a cluster, processing real-time data, and writing your own Spark extensions.
Topics include:
- Analyzing, transforming, and visualizing data in Spark from R
- Fitting supervised and unsupervised models and combining them into pipelines
- Deploying clusters with on-premises managers, cloud providers, and Kubernetes
- Reading data from CSV, JSON, Parquet, Hive, Cassandra, and JDBC sources
- Tuning Spark jobs through configuration, partitioning, and caching
- Using extensions for graphs, XGBoost, deep learning, genomics, and spatial data
- Distributing custom R code across many machines
- Processing streaming data with Kafka and Shiny
The book is free to read online.


