

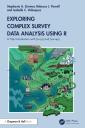

Survey data usually come with weights and design features such as strata and clusters, and analyzing them correctly requires methods that account for how the sample was drawn.
This book teaches complex survey analysis in R with the srvyr package, which wraps the long-established survey package in tidyverse-style syntax so that functions like filter(), mutate(), and summarize() work on survey design objects.
Where srvyr does not offer tidy wrappers, as with most modeling and hypothesis tests, the book uses survey directly.
It is written for analysts who already know R and the tidyverse but are new to survey analysis. Alongside the code, it explains the statistical ideas behind the functions, from survey design and documentation to sampling designs, replicate weights, and missing data. Examples use public data from the American National Election Studies and the Residential Energy Consumption Survey, and two closing vignettes walk through full analyses of the National Crime Victimization Survey and AmericasBarometer. The book assumes weights already exist and does not cover how to create them.
Readers learn how to:
- Read survey documentation and set up survey design objects
- Calculate point estimates, standard errors, confidence intervals, and design effects
- Compare means and proportions and run chi-square tests
- Fit linear regression, ANOVA, and logistic regression models to survey data
- Specify common sampling designs and replicate weight methods
- Handle missing data and skip patterns
- Communicate results with publication-ready tables and graphs
- Make survey analyses reproducible
The book is free to read online, and its analytic data sets are available in the companion srvyrexploR package.

