

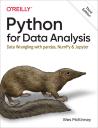

Written by Wes McKinney, the creator of the pandas project, this book is a practical guide to manipulating, processing, cleaning, and crunching data in Python.
It suits analysts who are new to Python as well as Python programmers who are new to data science and scientific computing.
The third edition brings the content up to date with the many changes in pandas since 2017.
The print edition targets Python 3.10 and pandas 1.4, and the open access online edition has since been updated for pandas 2.0.
The book starts with the essentials of the Python language, its built-in data structures, and working in IPython and Jupyter, then turns to array-oriented computing with NumPy before spending most of its pages on pandas.
It closes with a series of detailed case studies on real datasets, such as US baby names and federal election contributions, that bring the techniques together.
You will learn how to:
- Use Jupyter notebooks and the IPython shell for exploratory computing
- Work with
NumPyarrays and vectorized computation - Load data from text files, binary formats, web APIs, and databases
- Clean, transform, merge, and reshape datasets with
pandas - Create visualizations with
matplotlibandseaborn - Summarize data with group operations, pivot tables, and cross-tabulation
- Analyze regular and irregular time series
- Get started with modeling libraries such as
statsmodelsandscikit-learn
An open access HTML version is free to read online, and the code examples and datasets are available on GitHub.