

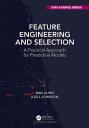

After Applied Predictive Modeling, Max Kuhn and Kjell Johnson turned to a part of the modeling process that most resources overlook: how the predictors themselves are represented. A model can disappoint not because the algorithm is wrong but because important relationships are hidden in transformations, interactions, or alternative encodings of the data. This book gathers tools for finding better representations of predictors and for choosing the most useful subset of them, and it places those tools within a sound modeling framework that guards against overfitting.
The authors treat feature engineering as closer to an art than a fixed recipe, and they share lessons from their own applied work. Techniques are illustrated with real data sets, including stroke risk, Chicago train ridership, OkCupid profiles, pharmaceutical manufacturing, and Parkinson’s disease, and each chapter ends with notes on computing in R.
Topics include:
- Reviewing the predictive modeling process, including resampling and tuning
- Using exploratory visualizations to guide feature engineering
- Encoding categorical predictors, including those with many categories and text
- Transforming numeric predictors
- Detecting interaction effects
- Handling missing data
- Working with profile data
- Selecting features with filters, recursive feature elimination, simulated annealing, and genetic algorithms
The book is free to read online, and the data sets and R code needed to reproduce the results are available on GitHub.
